

Managed SOC Services: Your 2026 Selection Guide
The managed security services market is projected to reach US$ 87.9 Billion by 2033, up from US$ 41.3 Billion in 2026 at an 11.4% CAGR according to Persistence Market Research. That number matters because it reframes managed SOC services from a niche outsourcing decision into a mainstream operating model for security teams that can't afford blind spots, delayed response, or constant hiring battles.
Most internal teams don't fail because they lack tools. They fail because security operations is a grind. Alerts keep arriving, the environment keeps changing, and the people who understand the stack are also the same people expected to handle architecture, audits, cloud reviews, and incident calls. That's why more leaders are looking at managed SOC services as an operating decision, not just a product buy.
If you're responsible for selecting or reshaping security operations, it helps to ground the discussion in the day-to-day realities of protecting businesses from cyber threats, especially when your estate spans cloud platforms, endpoints, identity systems, and on-prem infrastructure. It also helps to understand the persistent operational burden described in UTMStack's review of top cybersecurity pain points, because most SOC sourcing decisions start there.
Table of Contents
- The Rise of the Outsourced Security Operations Center
- Deconstructing Managed SOC What You Actually Get
- Choosing Your Model In-House vs Co-Managed vs Fully Managed
- Integrating with Your SIEM XDR and SOAR Stack
- The Business Case Benefits vs Risks of Outsourcing
- How to Choose a Managed SOC Partner A Vendor Checklist
- Implementation Roadmap and Real-World Use Cases
- Conclusion Your Next Steps in Security Operations
The Rise of the Outsourced Security Operations Center
Cybersecurity Ventures expects the global cyber workforce gap to reach millions of unfilled roles this decade, and that hiring pressure shows up fast inside security operations teams. A 24×7 SOC needs more than a few strong analysts. It needs repeatable coverage, detection engineering, incident handling, platform administration, and enough depth to keep those functions running during turnover, vacations, and major incidents. For many organizations, outsourcing part of that load has become a staffing decision first and a tooling decision second.
The shift is not just about cost. It is about operating reality.
Security leaders are being asked to monitor cloud workloads, identity systems, endpoints, SaaS apps, remote users, and third-party connections with the same team that also owns audits, policy work, and internal projects. Many teams can build a capable daytime operation. Fewer can sustain nights, weekends, tuning, and response quality over time without burning people out.
Why now
Three pressures usually drive the move toward an outsourced or co-managed SOC.
- Coverage that holds up after hours: Attackers work around your staffing model. If the queue waits until morning, dwell time and business impact usually grow with it.
- Hybrid stack complexity: Security operations now span Microsoft and Linux endpoints, cloud-native telemetry, identity providers, firewalls, SaaS audit logs, and often an existing SIEM or XDR that the business does not want to replace.
- Audit and reporting demands: Regulators, customers, and cyber insurers increasingly ask for evidence of monitoring, escalation, case handling, and follow-through, not just proof that tools were purchased.
The practical trigger is usually operational pain. Teams start by adding another product, then another feed, then another dashboard. Eventually they hit the point described in these top cybersecurity pain points identified in internet trends analysis: too many alerts, too little context, and too much manual effort to connect the data into usable action.
What changed in buyer expectations
Buyer expectations are sharper than they were a few years ago. Security teams used to accept outsourced alert monitoring if it reduced noise. That is no longer enough. The current buying standard is closer to co-managed operations built around the stack you already own, especially in hybrid environments where cloud telemetry, on-prem systems, and open-source tooling all need to work together.
That matters for organizations running Elastic, Wazuh, Security Onion, Microsoft Sentinel, Splunk, or a mix of native cloud controls with SOAR playbooks layered on top. A provider that only works inside its own closed platform creates a second operations silo. A provider that can ingest your telemetry, tune detections in your SIEM or XDR, and share workflows with your internal team usually creates more long-term value.
I have seen this distinction decide the outcome of vendor selections. The question is not whether the provider has a SOC. The question is whether that SOC can operate inside your environment without forcing a rip-and-replace program you did not budget for.
A good outsourced SOC arrangement can strengthen resilience while keeping internal ownership over risk decisions, sensitive systems, or regulated response actions. That is why the market keeps growing. Organizations want better execution, better coverage, and a practical way of protecting businesses from cyber threats without rebuilding every SOC function internally.
Deconstructing Managed SOC What You Actually Get
A managed SOC is an operating function, not a mailbox for alerts. You are buying people who investigate, processes that define response authority, and technology that ties your telemetry to action. If a provider only forwards notifications from its own console, you still carry the hard part internally.

The practical question is simple. What work does the provider take off your team, and what work still stays with you at 2 a.m. during an incident?
People, process, and technology
People define whether the service is operationally useful. A serious managed SOC includes tier 1 and tier 2 analysts for triage, detection engineers who can tune rules in your actual stack, and senior responders for cases that need judgment rather than a canned playbook. In co-managed models, named contacts matter. You want to know who owns detection changes, who runs service reviews, and who can approve a containment action when your internal lead is unavailable.
Process determines whether the service holds up under pressure. Good providers document triage thresholds, escalation paths, evidence handling, containment options, change control, and post-incident review. They also spell out decision rights. If account disablement, host isolation, or ticket closure rules are vague in the statement of work, expect delays and finger-pointing during a live event. For teams refining that side of the operating model, this overview of critical incident response services guidance is a useful reference because it treats response as repeatable operations, not a one-off project.
Technology is where many evaluations go wrong. The question is not whether the provider has a portal. The question is whether the provider can work inside the stack you already run, especially across hybrid environments and open-source tooling. That means support for your SIEM, XDR, EDR, SOAR, cloud telemetry, identity signals, and ticketing workflow. If your team is building around Elastic, Wazuh, Security Onion, Microsoft Sentinel, Splunk, or a mixed stack, ask whether the provider tunes detections there, ingests custom logs there, and documents use cases there. Teams exploring a cost-conscious operating model can compare that approach with this guide to building a 24/7 SOC with free and open-source technologies.
A provider that insists on moving all operations into a closed platform creates a second control plane. That can simplify service delivery for the vendor, but it often makes investigations slower for your internal team and weakens long-term knowledge transfer.
What usually stays on your side
Even in a fully managed service, internal ownership does not disappear. The provider can monitor, investigate, and in some cases contain. You still own business risk, production change approval, privileged access decisions, and any response step that could affect regulated data, customer-facing systems, or legal exposure.
A workable split usually looks like this:
| Responsibility | Usually provider-led | Usually client-led |
|---|---|---|
| Monitoring and triage | Yes | Sometimes in co-managed setups |
| Detection tuning | Shared | Shared |
| Containment actions | Shared by playbook | Approval and business risk decisions |
| Root cause analysis | Often provider-led | Shared with system owners |
| Compliance evidence review | Shared | Final accountability remains internal |
The strongest providers make this boundary explicit before onboarding. They define which playbooks they can execute directly, which ones require approval, and which systems are out of scope because of safety, compliance, or operational risk.
One more point gets missed in buyer conversations. A managed SOC should improve your security content over time. After incidents, the provider should adjust detections, reduce false positives, add enrichment, and document gaps in logging or asset coverage. That matters even more in co-managed environments, where the value is not just round-the-clock monitoring. The value is a service model that improves the stack you already own instead of replacing it.
Choosing Your Model In-House vs Co-Managed vs Fully Managed
The right model depends less on ideology and more on operating constraints. Some organizations need sovereign control because of internal policy or specialized environments. Others need relief from round-the-clock operations. Most sit in the middle.

The market signal is clear. The SOC as a Service market is projected to reach USD 23.91 billion by 2034, and the large enterprise segment is projected to hold 58.45% of the market share in 2026, according to Fortune Business Insights. Large and complex organizations aren't outsourcing because security is simple. They're doing it because complexity makes selective outsourcing practical.
Where each model fits
Here's the blunt version.
| Model | Best fit | Strength | Main drawback |
|---|---|---|---|
| In-house | Large teams with mature staffing and deep internal process discipline | Full operational control | Expensive to sustain and hard to staff continuously |
| Co-managed | Teams that want to retain oversight but offload 24×7 operations or specialist functions | Balance of context and coverage | Requires clear role boundaries |
| Fully managed | Organizations that need fast coverage with limited internal SOC capacity | Lower internal overhead | Risk of losing business context if the provider operates too far from the environment |
An in-house SOC works when the organization already has the people, tuning discipline, leadership support, and budget stability to run operations continuously. The upside is direct control over telemetry, workflows, and prioritization. The downside is that every capability has to be staffed, trained, covered, and maintained internally.
A fully managed SOC works when coverage is the immediate problem. This model can reduce operational burden quickly, but it can also drift into shallow service delivery if the provider doesn't understand your asset criticality, business processes, or change windows.
Why co-managed often wins
Co-managed tends to fit actual environments best, especially in hybrid estates. The internal team keeps what only it can do well. Business context, executive communication, change approval, and final risk decisions. The provider takes on sustained monitoring, triage, playbook execution, specialized investigations, or after-hours coverage.
That structure is especially useful if you're already building with flexible tooling, including open-source options. Teams exploring that route can compare the staffing burden against the architecture in UTMStack's guide to building a 24/7 SOC with free and open-source technologies. The technical stack is only half the equation. The other half is who runs it at 2 a.m.
A co-managed SOC only works when both sides agree on escalation depth, authority to act, and ownership of tuning. Without that, shared responsibility becomes shared confusion.
A practical test is simple. If your current team can handle strategy, architecture, and high-severity decision-making but can't maintain constant operational pressure, co-managed is usually the strongest candidate.
Integrating with Your SIEM XDR and SOAR Stack
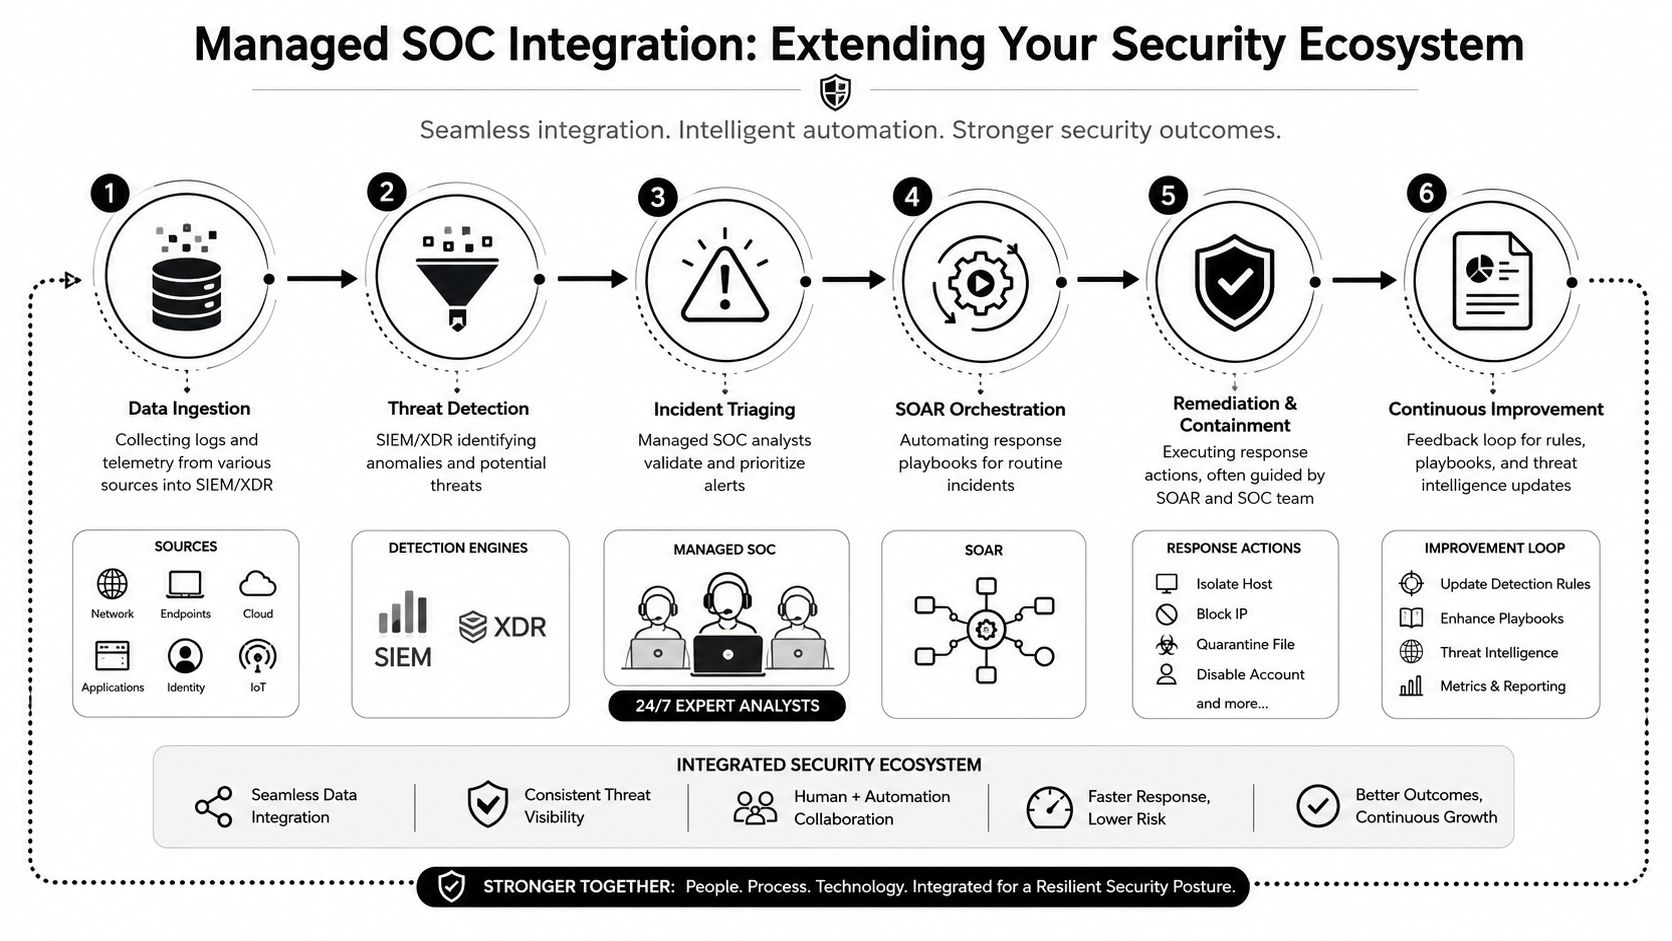
Integration is where many managed SOC deals either become useful or become expensive disappointment. The provider shouldn't operate as a detached console that sees only partial telemetry. It should extend the tools and data sources you already trust, whether they live on-prem, in cloud platforms, or across both.
How the data flow should work
The healthy pattern looks like this.
- Ingestion starts broadly. Logs and telemetry arrive from endpoints, identity providers, firewalls, cloud services, SaaS applications, vulnerability scanners, and core infrastructure.
- Correlation happens centrally. The SIEM or XDR layer links related signals into a case-worthy event instead of a pile of unrelated alerts.
- Analysts validate context. The managed SOC team decides whether the alert reflects malicious activity, operational noise, or a control gap.
- SOAR playbooks execute defined actions. That may include enrichment, ticket creation, user disablement requests, host isolation, or blocking indicators where authority exists.
- Findings feed back into tuning. Detections improve only when false positives, missed context, and response friction are folded back into rules and playbooks.
That feedback loop is where strong providers earn their keep. Managed SOC services aren't just about watching telemetry. They're about making your telemetry operational.
Open-source and hybrid reality
Hybrid estates complicate everything. Some logs come through APIs, others through Syslog or agents. Cloud control-plane events behave differently from endpoint telemetry. Identity alerts may be high value but low volume. Network devices often produce a lot of noise and little context unless correlation is tuned carefully.
That's why I prefer vendors that can work with the client's existing stack instead of insisting on a proprietary silo. If your team uses an open-source or mixed environment, the provider should support it with clean onboarding, field mapping, parser maintenance, and shared detection logic. One example is UTMStack, which combines SIEM, SOAR, and XDR functions for hybrid environments and can serve as part of a managed or co-managed operating model. The point isn't the brand. The point is flexibility.
A provider that can't explain how it handles these integration questions will create friction fast:
- Data ownership: Who keeps the raw logs, normalized records, detections, and case history?
- Bidirectional actions: Can the SOC trigger containment in your current endpoint or identity tools?
- Parser and schema control: Who maintains field mappings when cloud services or devices change formats?
- Open export paths: Can you move detections, cases, and evidence elsewhere if the relationship ends?
Your SIEM is not your SOC. Your XDR is not your response process. Managed SOC services create value only when people, tooling, and workflows are wired together cleanly.
If a provider answers integration questions with marketing language instead of workflow detail, that's a warning sign.
The Business Case Benefits vs Risks of Outsourcing
Organizations that outsource security operations usually do it for one reason. The cost of missed alerts, slow triage, and analyst burnout is higher than the cost of the service.
That business case holds up only if the provider fits your environment. In hybrid estates, the question is not just whether a managed SOC is cheaper than hiring around the clock. The true question is whether the provider can work inside your current SIEM, XDR, SOAR, cloud telemetry, identity controls, and ticketing flow without forcing an expensive rebuild. That is why co-managed models often make more financial sense than a full handoff. They preserve internal context while shifting repetitive monitoring and first-line response to a partner.
Where the value shows up
The return usually appears in four places.
- Lower staffing pressure: Building true 24×7 coverage internally means recruiting, training, scheduling, and retaining analysts across all shifts. Many teams underestimate that burden until turnover hits.
- Better use of senior talent: Internal engineers and architects spend less time clearing noisy queues and more time fixing root causes, tuning controls, and reducing attack surface.
- More consistent operations: A mature provider can keep triage, escalation, and case handling stable during nights, weekends, vacations, and internal reorganizations.
- Stronger evidence trails: Good providers document alerts, investigations, and response actions in a way that helps with audits, incident reviews, and board reporting.
The hidden gain is focus. Security teams often know what they should improve, such as identity hygiene, segmentation, cloud guardrails, or logging coverage, but they never get the time. Outsourcing part of the SOC function can create that time.
There is also a stack-level benefit that buyers miss. A provider that supports open-source or mixed platforms can extend the life of tools you already own. If the service can operate in your SIEM or ingest from products like UTMStack alongside commercial controls, you avoid paying twice for monitoring, once in software and again in a bundled black-box service.
Where outsourcing breaks down
The biggest risk is context loss.
An external analyst can follow the playbook and still misread business impact. A privileged login after midnight might be normal for your infrastructure team, but a high-risk indicator for finance or HR. If asset criticality, user roles, and exception patterns are not maintained well, the provider will either escalate too much noise or miss what matters.
Authority is the second failure point. Response slows down fast when nobody has defined who can disable an account, isolate a host, block an IP, or approve a cloud containment action. I have seen this derail otherwise solid SOC programs. The tooling was in place. The contract was signed. The decision rights were still vague.
The third risk is false coverage. A managed SOC does not fix missing logs, poor endpoint visibility, weak identity controls, or stale asset inventory. It can expose those problems quickly, but it cannot compensate for them indefinitely.
The practical trade-off
Outsourcing works best when you treat it as an operating model decision, not a procurement shortcut. Fully managed service can reduce internal load the most, but it also creates the highest dependency on the vendor's processes and assumptions. Co-managed service takes more effort from your team, yet it usually gives better results in hybrid environments because internal staff keep ownership of business context, tuning priorities, and containment approvals.
That is the evaluation lens I recommend. Do not ask only, "Will this lower cost?" Ask these questions instead:
- What work leaves my team, and what work stays?
- Can the provider support our current SIEM, XDR, and open-source data sources without forcing platform replacement?
- Who owns detection tuning, parser fixes, and log quality when data formats change?
- What response actions can the provider take without waiting for approval?
- How hard will it be to exit the relationship without losing detections, case history, and operational knowledge?
A sound business case includes both savings and friction. If a vendor can show clear coverage, defined responsibilities, and clean integration with your existing stack, outsourcing can improve response quality and free internal teams for higher-value security work. If those conditions are missing, you are not buying efficiency. You are buying another coordination problem.
How to Choose a Managed SOC Partner A Vendor Checklist
Managed SOC buyers often underestimate one decision point. The hard part is not confirming that a provider has a 24×7 queue. The hard part is confirming that the provider can operate inside your stack, your escalation rules, and your response boundaries without creating delay or forcing a tooling reset.

That gap shows up most clearly in hybrid and co-managed environments. UnderDefense notes that many organizations now run hybrid security operations, yet pricing and responsibility splits for co-managed service often remain vague in the sales process (UnderDefense). That is a procurement risk, but it is also an architecture risk. If a vendor cannot describe shared ownership clearly, expect confusion around tuning, approvals, and incident handoffs once the service goes live.
Strong providers stand out in operational details, not brochure language. They can explain how they ingest data from commercial and open-source tooling, how they maintain parsers when formats change, and how they avoid breaking existing detection logic in a client-owned SIEM, XDR, or SOAR stack. They also show where their analysts stop and where your team must step in.
The checklist that matters
Use this checklist in demos, RFPs, and technical validation calls.
- Role clarity: Get a written RACI for monitoring, triage, investigation, tuning, containment approval, evidence collection, and service review.
- Integration fit: Ask how the service connects to your SIEM, XDR, SOAR, identity platform, ticketing system, cloud telemetry, and network controls. Ask the same question for open-source components if you run them.
- Detection ownership: Confirm who writes and tunes detections, who maintains correlation rules, and who fixes broken parsers or field mappings.
- Threat hunting capability: Verify whether threat hunting is scheduled analyst work with hypotheses and reporting, or just marketing language wrapped around alert review.
- Analyst depth: Ask how cases move from Tier 1 triage to senior investigation, malware analysis, or incident coordination.
- Vulnerability linkage: Check whether exposure data can affect detection priority, alert routing, or investigation context.
- Compliance outputs: Request sample reports, audit artifacts, case notes, and evidence packages that match your regulatory requirements.
- Pricing transparency: Require a line-by-line explanation of what changes in a co-managed model if your team keeps part of triage, approvals, engineering, or incident response.
One practical test helps separate mature vendors from noisy ones. Ask them to walk through a detection failure caused by a log schema change in a hybrid environment. A capable provider will explain ownership, turnaround time, validation steps, and rollback procedure. A weak provider will default to general statements about platform coverage.
RFP questions worth asking
Direct questions produce better answers.
- Which detections do you own and tune, and which remain under client control?
- How do you support hybrid cloud, on-prem, and open-source telemetry without requiring platform replacement?
- What response actions can you take directly, and what requires explicit client approval?
- Who maintains parsers, field mappings, and normalization logic as data sources change over time?
- How do you measure alert quality, false-positive rate, investigation depth, and incident outcomes each month?
- How does pricing change if our internal team keeps part of triage, engineering, or incident handling?
- How do you export detections, case data, runbooks, and service knowledge if we change provider or bring operations back in-house?
I also recommend asking for a working session with the people who will run the service, not just the sales team. Review one alert flow, one tuning workflow, and one escalation path tied to your current stack. If the provider cannot show how their SOC works with your environment as it exists today, the partnership will be harder than it looks on paper.
Treat co-managed pricing and integration design as one evaluation topic. Cost only makes sense after responsibilities, tool ownership, and response authority are defined.
The strongest shortlist usually comes from vendors that answer operational questions with precision, document trade-offs openly, and support the stack you already run, including hybrid and open-source components, instead of pushing unnecessary replacement.
Implementation Roadmap and Real-World Use Cases
SOC transitions usually fail for operational reasons, not tooling reasons. The common pattern is familiar. Teams connect data before they define ownership, turn on detections before they test routing, and expect an external analyst team to infer business risk from logs alone.
A managed SOC rollout works better when the service is treated as an operating model change with technical dependencies, not as a monitoring add-on. That matters even more in hybrid environments where the stack already includes a mix of cloud controls, on-prem infrastructure, and open-source or partially customized SIEM, XDR, and SOAR components.
A practical rollout path
I usually break implementation into four working phases.
Phase 1: Scope and control design. Start with asset groups, identity providers, cloud accounts, network boundaries, compliance obligations, and incident contacts. Then define who owns triage, who can contain hosts or disable accounts, and which systems stay under internal approval. In co-managed models, this step decides whether the provider becomes useful fast or spends months waiting on clarification.
Phase 2: Data onboarding and validation. Connect telemetry, then verify parser quality, field mappings, timestamps, enrichment, and tenant separation. At this stage, hybrid and open-source stacks need extra attention. A provider may say it supports your SIEM or data lake, but the crucial test is whether it can work with your current schemas, custom collectors, and uneven log quality without forcing a platform replacement.
Phase 3: Detection tuning and workflow alignment. Tune detections against real activity, not vendor defaults. Validate case severity rules, after-hours handling, suppression logic, and approval gates for response actions. If the provider uses its own portal while your team works from another SIEM, XDR console, or ticketing system, map that handoff now before incidents expose the gaps.
Phase 4: Steady-state operations. Run monthly reviews on alert quality, missed coverage, response times, parser drift, and closed-loop incident outcomes. This is also the point to decide what engineering stays internal. Many teams keep content tuning for business-specific detections while the provider handles monitoring and first-pass investigation.
Use case for a regulated enterprise
A mid-sized healthcare organization often lands in a co-managed model for practical reasons. The internal team understands clinical workflows, privileged access risk, and change windows. It usually does not have the staff depth for continuous monitoring, overnight investigation, and sustained detection engineering at the same time.
A workable design splits duties with precision. The provider handles 24×7 monitoring, triage, and initial investigation across identity, endpoint, firewall, and cloud telemetry. Internal staff keep authority over clinical systems, downtime-sensitive assets, legal review, and executive communications. That separation reduces coverage gaps without giving an outside team uncontrolled response authority in sensitive environments.
The integration details matter more than the service label. If the organization already runs a mix of commercial endpoint tools, cloud-native logs, and an open-source SIEM layer, the provider has to meet the stack where it is. Strong providers can normalize that telemetry, preserve audit evidence, and push case data back into the client's existing systems. Weak providers ask for a rip-and-replace project before they can operate.
What good looks like in practice:
- Overnight alerts are triaged by someone accountable for response, not left for the morning shift.
- Incident records include timestamps, analyst notes, and containment decisions that hold up during audits.
- Vulnerability findings are reviewed with live detection context, so exposed systems with active signs of abuse move to the top of the queue.
- Internal teams spend less time reconciling multiple consoles and more time deciding on business-impacting actions.
Use case for an MSP
MSPs face a different scaling problem. They may already manage endpoints, firewalls, cloud services, and backups for multiple clients, but lack enough experienced analysts to deliver credible SOC coverage across all tenants.
In that model, the managed SOC partner has to fit inside an existing service business, not compete with it. The MSP keeps client ownership, service packaging, and account coordination. The SOC partner contributes monitoring, investigation depth, threat hunting, and documented response procedures.
Three design decisions usually determine whether the arrangement holds up under pressure:
- Multi-tenant operations: Client data, detections, and cases must stay separated while analysts still work efficiently across tenants.
- Shared workflow control: The MSP needs clear rules for what the SOC can act on directly, what requires MSP approval, and what must go to the end client.
- Tool compatibility: If the MSP uses an open-source SIEM, a shared XDR console, or a custom ticketing workflow, the SOC partner should integrate with it instead of forcing every client into the provider's preferred stack.
Vendor evaluations frequently lack depth. For MSP and co-managed deployments, the key question is not whether the provider offers SIEM, XDR, or SOAR features. The question is whether it can operate cleanly across your hybrid telemetry sources, preserve data ownership boundaries, and support shared responsibility without constant manual workarounds.
A practical evaluation framework is simple. Ask the provider to show one tenant onboarding flow, one parser change process, one cross-tool investigation, and one approval-based containment action using a stack that resembles yours. If that demo breaks down when open-source components or client-owned tooling enter the picture, the operating model will break later too.
The best implementations are rarely the ones with the most features. They are the ones where data onboarding is clean, responsibilities are explicit, and the provider can work inside the hybrid stack you already run.
Conclusion Your Next Steps in Security Operations
Managed SOC services make sense when security operations has become bigger than the internal team's available time, coverage, or specialization. The key decision isn't whether outsourced monitoring sounds attractive. It's whether your organization needs in-house control, a co-managed partnership, or a fully managed service with minimal internal overhead.
The strongest outcomes come from three choices made early. Pick the right delivery model. Make sure the provider can integrate with your existing SIEM, XDR, and SOAR stack. Force clarity on roles, escalation authority, and co-managed pricing before the contract is signed.
Start with the checklist. Review your current telemetry, staffing limits, and incident workflows. Then ask vendors to show how they'd operate inside your environment, not just in their demo portal.
If you're comparing platforms for a co-managed or managed SOC model, UTMStack is one option to review. It combines open-source SIEM, SOAR, and XDR capabilities for hybrid environments, which makes it relevant when you need flexible integrations, shared response workflows, and compliance-oriented visibility without forcing a closed tooling model.


