Analysts summarized by the PCI Security Standards Council found that breaches in scope for PCI frequently involved card data. Teams already know the risk. The hard part is proving, month after month, that the controls around that data stayed in place and kept working.
That is why many PCI DSS audits stall in the same places: scattered evidence, undocumented scope changes, firewall rules that drifted after a change window, and logs that exist but were never centralized. By the time the assessor asks for proof, the security team is pulling from tickets, exports, screenshots, scan results, and archived logs instead of producing a clean record from one system.
A useful PCI DSS compliance checklist has to do more than tell you what the twelve requirements say. It should tell you how to collect evidence, how to monitor control drift, and how to show an auditor that the control operated continuously. PCI DSS 4.0 raises that bar. Point-in-time screenshots are weaker evidence than a system that records changes, alerts on exceptions, and keeps the audit trail intact.
This checklist is built that way. Each requirement is paired with a SIEM/XDR workflow that turns a manual control into an observable one: firewall changes sent to a central console, default-account detections tied to asset inventory, access events correlated with identity data, and malware or vulnerability findings retained as audit evidence. With a platform such as UTMStack, teams can combine log collection, alerting, case management, and network device monitoring for firewall and infrastructure visibility instead of treating PCI as a once-a-year document chase.
That approach changes the trade-off. You still need policy, ownership, and technical controls, but you spend less time assembling evidence by hand and more time fixing gaps while they are still small. For security teams running hybrid, SaaS-heavy, or fast-changing environments, that difference usually decides whether PCI becomes a repeatable process or an annual fire drill.
1. Requirement 1 Install and Maintain Firewall Configuration
The first control is still one of the easiest to misunderstand. Teams often think “firewall” and hand the requirement to the network group. Auditors don’t stop at the device config. They want to see segmentation logic, rule review, change history, and evidence that traffic between the cardholder data environment and everything else is explicitly controlled.
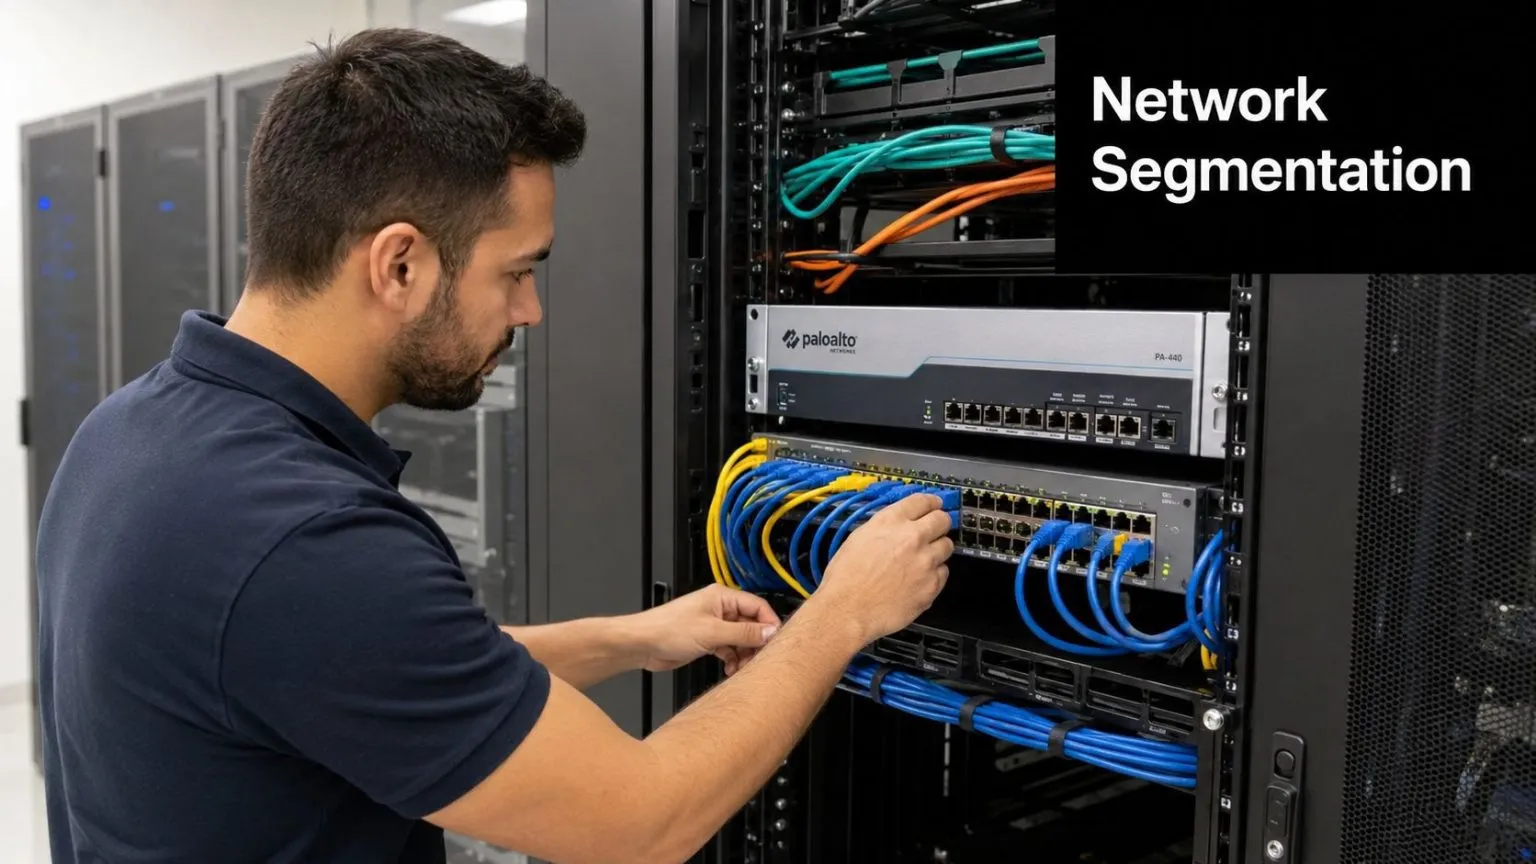
In practice, Palo Alto Networks, Fortinet, Check Point, and Cisco firewalls can all satisfy this area if the team enforces deny-by-default policy, documents allowed flows, and reviews changes with discipline. What fails most often isn’t the platform. It’s undocumented exceptions and stale rules that stayed in place after a project ended.
Boundary control that auditors can actually verify
A strong operating pattern is to send firewall logs, config-change events, and admin actions into a SIEM so you can prove both design and operation. With network device monitoring in UTMStack, teams can centralize events from firewalls, switches, and other network infrastructure, then correlate rule changes with change tickets and admin sessions instead of reviewing each source manually.
Useful checks in this requirement include:
- Map the CDE boundary clearly: Document which subnets, VLANs, cloud security groups, and VPN paths are in scope.
- Review exceptions aggressively: Temporary allows become permanent risk if nobody expires them.
- Log administrator activity: Rule changes without named accountability create audit friction immediately.
- Watch east-west traffic: Segmentation isn’t proven by perimeter controls alone.
Practical rule: If you can’t show who changed a firewall rule, why they changed it, and what traffic hit that rule afterward, you’re not audit-ready.
The trade-off is maintenance. Granular segmentation reduces exposure, but it increases rule volume and review time. That’s manageable when the SIEM tags rule changes, highlights unexpected traffic paths, and preserves evidence continuously. Without that, firewall compliance becomes a screenshot exercise, and screenshot compliance rarely survives real scrutiny.
2. Requirement 2 Do Not Use Vendor-Supplied Defaults for System Passwords
This requirement sounds basic because it is basic. It’s also one of the controls teams accidentally break during rollouts, migrations, appliance swaps, and emergency rebuilds. Default accounts, preset SNMP strings, factory web interfaces, and inherited service credentials still show up in environments that otherwise look mature.
The tool choice here matters less than the process. Microsoft Intune, Jamf, Red Hat Satellite, Ansible, Puppet, and Chef all help standardize secure baselines. Vulnerability scanners such as Tenable, Rapid7, and Greenbone help detect weak configurations after deployment. The gap is usually between build standards and production drift.
Defaults come back during change windows
The safest pattern is to treat secure configuration as a repeatable baseline, not a one-time hardening task. Build images should remove or disable default accounts before production. Post-deployment checks should verify that unnecessary services are still disabled, web admin consoles aren’t exposed, and local admin credentials haven’t drifted away from policy.
What works well:
- Standard images and templates: Harden once, reuse often.
- Configuration drift monitoring: Catch reintroduced defaults after patching or appliance replacement.
- Asset inventory tied to ownership: Someone must own each device class, including payment appliances.
- Exception logging: Legacy systems with limited password options need compensating controls and documented handling.
What doesn’t work is relying on policy alone. Staff under delivery pressure will take shortcuts if the deployment pipeline doesn’t enforce the baseline.
A practical auditing point: don’t just prove defaults were changed. Prove you have a way to detect when defaults return. That’s especially important in PCI DSS 4.0 environments where continuous validation matters more than annual declarations. If your PCI DSS compliance checklist still treats Requirement 2 as a commissioning task, it’s behind reality.
3. Requirement 3 Protect Stored Cardholder Data
Requirement 3 is where good architecture saves more effort than good paperwork. If teams can reduce stored cardholder data through tokenization, truncation, or better payment flow design, every downstream control becomes simpler. If they store more than they need, encryption alone won’t rescue the audit.
The operational challenge isn’t only choosing cryptography. It’s discovering where data ended up: databases, exports, backups, object storage, email attachments, support tooling, and old reporting jobs. Teams that skip discovery often encrypt the primary datastore while leaving secondary copies exposed.
Reduce what you store before you encrypt what remains
Encryption platforms such as HashiCorp Vault, cloud KMS services, Thales, and payment tokenization providers are useful. But the highest-value question is simpler: why does this system still retain cardholder data at all?
One industry guide notes that PCI Council requirements are organized into 6 control categories, 12 steps, and more than 250 sub-requirements affecting 400+ security controls, and it also notes that merchants complete a Self-Assessment Questionnaire annually (PayJunction PCI DSS checklist guide). That’s a useful reminder that stored-data protection is never just an encryption checkbox. It creates evidence obligations across inventory, access control, key management, scanning, logging, and disposal.
For this requirement, the most effective evidence set usually includes:
- Data discovery results: Show where PAN-related data exists and where it doesn’t.
- Key access logs: Prove who accessed key material or key management systems.
- Backup handling records: Encrypted primary storage doesn’t help if backups are unmanaged.
- Retention and deletion proof: Expired business need should trigger removal, not archival.
Store less, segment more, and make key access visible. That combination reduces both breach impact and audit scope.
The trade-off is application complexity. Tokenization and field-level protection can complicate integrations, reporting, and troubleshooting. But from an auditor’s perspective, fewer places storing sensitive data is almost always the cleaner answer.
4. Requirement 4 Encrypt Cardholder Data in Transit Across Public Networks
Teams usually pass this requirement at the browser edge and fail it in the less obvious places. Internal APIs crossing untrusted links, admin sessions to payment infrastructure, vendor tunnels, backup transfers, and message queues often get less attention than the public payment page.
A good tool stack here includes certificate management, vulnerability scanning, reverse proxy controls, and SIEM visibility into failed handshakes, protocol mismatches, and deprecated ciphers. F5, NGINX, HAProxy, cloud load balancers, Venafi, and native cloud certificate managers all fit, depending on architecture.
Certificate hygiene is part of compliance hygiene
Strong transport encryption only works when certificate inventory and renewal are disciplined. Teams should monitor certificate age, issuer, expiration, and deployment consistency across every in-scope endpoint, not only customer-facing ones. Admin traffic matters too. SSH, HTTPS administration panels, API gateways, and remote support channels all deserve the same scrutiny.
A few practical review points make this requirement easier to sustain:
- Find unmanaged certificates: Old internal services are frequent blind spots.
- Disable weak protocols consistently: One forgotten endpoint creates audit questions fast.
- Log TLS failures centrally: Repeated failures can indicate misconfiguration or active probing.
- Validate after changes: New proxies and service meshes often introduce accidental downgrade paths.
The trade-off is compatibility. Legacy clients and inherited business applications sometimes pressure teams to keep weaker settings alive longer than they should. When that happens, document the exception, isolate it, and plan a removal path. Don’t pretend the risk disappeared because a compensating narrative exists.
6. Requirement 6 Develop and Maintain Secure Systems and Applications
Requirement 6 usually exposes whether security evidence is tied to the software delivery process or scattered across separate tools. Teams may run SAST, DAST, dependency scanning, patching, and change control, yet still struggle in an audit because they cannot show one clear chain from finding to fix to production validation.
PCI DSS v4.0 puts more pressure on that chain. Custom code, third-party libraries, emergency patches, and approved exceptions all need records that hold up under review. Auditors will ask practical questions. What was found, who approved the change, when was it deployed, and how do you know production now matches the approved state?
GitHub Advanced Security, GitLab, Snyk, SonarQube, Burp Suite, Nessus, Qualys, Wazuh, and standard patch platforms can all support this requirement. The hard part is correlation.
Build an auditable trail from code finding to production state
A workable process links four evidence types:
- Development findings: SAST, DAST, and software composition analysis results tied to a repository, branch, and commit.
- Change approval: Jira, ServiceNow, or another ticket that shows review, risk acceptance, and deployment approval.
- Deployment evidence: CI/CD logs, package versions, container image digests, or patch job results that show what changed.
- Runtime validation: File integrity monitoring, EDR, vulnerability rescans, and application logs from the production asset.
That linkage is where a SIEM or XDR platform stops being a log bucket and starts helping with Requirement 6. For example, UTMStack can ingest a Snyk alert for a vulnerable library, pull the related GitHub commit hash from the CI pipeline, match it to a Jira change ticket, and then correlate that ticket with a file integrity monitoring event on the production server that confirms the updated package or application file was deployed. Instead of four screenshots from four teams, you have one timeline.
That matters during both remediation and audit prep. Security can verify that a critical dependency issue was fixed within policy. Engineering can show that the deployed artifact matches the approved change. Audit staff can trace the record without chasing people through Slack and email.
Requirement 6 controls work better when evidence is continuous
For most organizations, the recurring review points are predictable:
- Patch high-risk systems on a defined timeline: Internet-facing assets and CDE-connected servers need stricter windows.
- Scan code and dependencies before release: Block or formally approve builds with critical findings.
- Review custom code changes: Peer review and secure coding checks need to be documented, not assumed.
- Validate production after deployment: Confirm the approved version, package, or container is what landed.
- Track exceptions and compensating controls: Legacy application constraints need owners, review dates, and a removal plan.
The trade-off is speed. Emergency fixes, fragile payment applications, and inherited codebases often force teams to choose between immediate change and full process discipline. PCI does not ban emergency action, but it does require you to prove the action was authorized, tested as far as feasible, and reviewed afterward. If that proof depends on manual collection, the process will break under pressure.
A SIEM/XDR workflow reduces that risk. Set correlation rules to alert when a production file changes without a matching approved ticket, when a critical CVE remains open after the patch SLA, or when a deployment occurs but the expected vulnerability closure never appears in the next scan. Those are concrete Requirement 6 checks, and they create evidence while the work is happening instead of a week before the assessor arrives.
Teams that handle Requirement 6 well treat secure development and secure operations as one control set. The checklist item is not “run scans.” The checklist item is proving that findings, fixes, approvals, deployments, and runtime state all line up.
6. Requirement 6 Develop and Maintain Secure Systems and Applications
Requirement 6 is where compliance and engineering discipline either reinforce each other or collide. If development, infrastructure, and security teams already run code review, vulnerability management, patch governance, and change control together, this area is manageable. If those processes are split across teams with separate tools and no shared evidence model, audits get messy fast.
SAST, DAST, software composition analysis, patch management, and file integrity monitoring all help here. GitHub Advanced Security, GitLab, Snyk, SonarQube, Burp Suite, Nessus, Qualys, and Wazuh are common pieces. None of them replace the need to tie findings to remediation and production state.
Tie development evidence to operational telemetry
A major shift under PCI DSS v4.0 is the emphasis on continuous monitoring and targeted risk analysis for customized approaches, which reflects the move from periodic compliance toward continuous assurance (Scale Computing overview of PCI compliance requirements). That matters most in Requirement 6 because custom applications and local exceptions create the exact kind of risk decisions that must be documented and defended.
The strongest approach is to connect these signals:
- Code and dependency findings: What was identified before release.
- Change records: What reached production and when.
- Runtime alerts: Whether the changed system later showed suspicious behavior.
- File integrity events: Whether critical files changed outside approved deployment paths.
A secure SDLC helps, but audit-ready evidence comes from proving that secure development controls stayed linked to production reality.
What doesn’t work is producing separate exports from dev tooling and hoping the assessor will mentally connect them. Central correlation is far more persuasive. When a patch was delayed, show the risk decision, compensating monitoring, and follow-up validation in one traceable chain.
7. Requirement 7 Restrict Access to Cardholder Data by Business Need-to-Know
Least privilege sounds straightforward until you inspect real group memberships. Access tends to accumulate around projects, support emergencies, contractor onboarding, and inherited roles. Months later, people still hold permissions nobody can justify.
Identity governance tools like Microsoft Entra ID, Okta, SailPoint, and CyberArk can make this cleaner. But even in well-tooled environments, auditors usually find the same weak spots: shared administrative pathways, broad support roles, and inconsistent review of privileged access to databases, payment gateways, and jump hosts.
Least privilege fails quietly unless you review it
This requirement benefits from role design that mirrors actual work, not org charts. Finance support, payment operations, developers, DBAs, and incident responders often need different slices of access, and lumping them together creates avoidable scope and evidence problems.
A practical review model looks like this:
- Define access by task, not by team name: “Can troubleshoot payment failures” is more useful than “belongs to IT operations.”
- Use time-bound elevation where possible: Permanent privilege is rarely necessary.
- Review access after role changes: Movers are often riskier than new hires.
- Correlate access with activity: Dormant privileged accounts are a recurring audit concern.
Another frequently missed issue is continuous scope validation. Checklist content often explains initial scoping, segmentation, inventory, and quarterly scans, but it rarely answers how to prove scope remained accurate after cloud changes and new connections. That gap is especially important in hybrid environments where scope drift can go undetected (XMCyber discussion of continuous PCI scope drift).
For Requirement 7, that means access reviews should include newly connected systems and services, not just the original in-scope list.
8. Requirement 8 Identify Users and Authenticate Access to System Components
Requirement 8 is often where auditors test whether your identity controls are operational or ceremonial. Unique IDs, MFA, session controls, and authentication logging are expected. A central question is whether you can reconstruct who accessed what, through which path, and under which level of assurance.
SSO platforms and MFA providers help, but they don’t finish the job by themselves. Okta, Duo, Microsoft Entra ID, Ping Identity, and CyberArk all support strong authentication. The audit burden remains: proving unique identification, tracking admin actions, removing stale accounts, and demonstrating that authentication events are preserved and reviewable.
Identity evidence has to survive the audit
A good practice is to centralize directory changes, failed login bursts, privilege elevation, remote admin events, and service-account usage into a single review workflow. That gives the assessor a consistent chain from identity to action. Teams that use UTMStack Access Rights Auditor can pull access-rights review data into the same compliance process that holds broader monitoring evidence, which reduces the usual scramble between IAM and security operations.
One point that often gets underexplained is cost and control selection. Public guidance usually lists the 12 requirements cleanly, but many teams still struggle with how to prioritize controls without over-engineering them. Recent guidance emphasizes targeted risk analysis, continuous monitoring, and evidence readiness, but it also leaves room for expensive mistakes if you automate the wrong things first (Thoropass discussion of PCI checklist tradeoffs and operating model design).
The most useful priorities in this requirement are usually:
- Unique IDs everywhere: Shared access breaks attribution.
- MFA on administrative and remote paths: This tends to reduce both real risk and audit pushback.
- Rapid deprovisioning: Former staff and stale contractors are still common findings.
- Authentication log retention: If the event trail is incomplete, the control story weakens.
10. Requirement 10 and 11 Track and Monitor All Access to Network Resources and Cardholder Data, Regularly Test Security Systems and Processes
A large share of PCI findings still trace back to weak logging, incomplete review processes, and testing that happens only right before the audit. Requirement 10 and 11 force a different operating model. Teams need to capture evidence continuously, detect suspicious activity quickly, and prove that controls were tested on schedule.
For PCI, that means keeping audit trails that can tie a user, system, or service account to a specific action. It also means running required security tests on a defined cadence and retaining the resulting records. If the logs exist but cannot be searched, correlated, or produced with context, the control is weaker than it looks.
A mature SIEM is the core of the operating model for these requirements. It collects logs from firewalls, servers, endpoints, cloud platforms, databases, identity providers, and payment applications, then keeps them in one place for review and retention. Used well, it reduces the usual audit problem: evidence spread across too many consoles, too many owners, and too much manual work.
The practical goal is not just ingestion. The practical goal is traceability.
For Requirement 10, collect and review events that matter to the cardholder data environment: authentication activity, privilege changes, policy changes, administrative actions, access to sensitive data, malware detections, and log tampering attempts. A platform with centralized log management for PCI evidence and investigations helps security teams keep those records searchable and aligned with retention expectations without building a separate process for every system.
For Requirement 11, testing has to feed the same evidence trail. Internal and external scans, file integrity monitoring, wireless checks where applicable, and penetration testing should not live in isolated folders that only appear during audit week. Scan outputs, exception tickets, remediation dates, and validation results should land in the same monitoring workflow as production alerts. That is how teams show not only that a test happened, but that results were reviewed and acted on.
One trade-off shows up quickly. If you alert on every authentication event and every port change, analysts burn time on noise and stop reviewing what matters. If you filter too aggressively, you miss the very records an assessor will ask for after an incident or failed control. The better approach is to tune for high-value events in the cardholder data environment first, then expand coverage once retention, ownership, and review discipline are stable.
Business Research Insights projects growth in the PCI compliance software market, which matches what many audit teams already see in practice: organizations are shifting from spreadsheet-based evidence collection to tools that support continuous monitoring and audit readiness. The spending alone does not fix the problem. Control mapping, alert tuning, and evidence retention still need deliberate design.
A workable checklist for these two requirements looks like this:
- Send all in-scope security logs to a central platform: Include network devices, servers, endpoints, IAM, databases, and payment applications.
- Verify time synchronization: Log timelines break down fast when systems drift.
- Retain logs according to PCI expectations: Keep recent data readily available for review and older data accessible for investigation and audit support.
- Define daily or scheduled review responsibilities: An assessor will ask who reviews alerts, what they review, and how exceptions are handled.
- Automate correlation for high-risk events: Privilege escalation, disabled logging, repeated failed access, suspicious remote administration, and changes to critical files should trigger review.
- Track testing artifacts in the same evidence process: Vulnerability scans, penetration tests, file integrity monitoring alerts, and remediation proof should be easy to retrieve.
- Document response and closure: Detection without investigation records creates unnecessary audit friction.
Teams usually struggle here because Requirement 10 and 11 expose operational gaps that other controls can hide. Logging has to be complete. Testing has to happen on time. Evidence has to be organized before the QSA asks for it. A SIEM/XDR-driven process turns that from a periodic scramble into a repeatable control.
10. Requirement 10 and 11 Track and Monitor All Access to Network Resources and Cardholder Data, Regularly Test Security Systems and Processes
These two requirements are where most PCI programs either mature or stall. Logging, alerting, scans, penetration testing, file integrity monitoring, and evidence retention are not separate side tasks. They are the system that proves every other control operated.
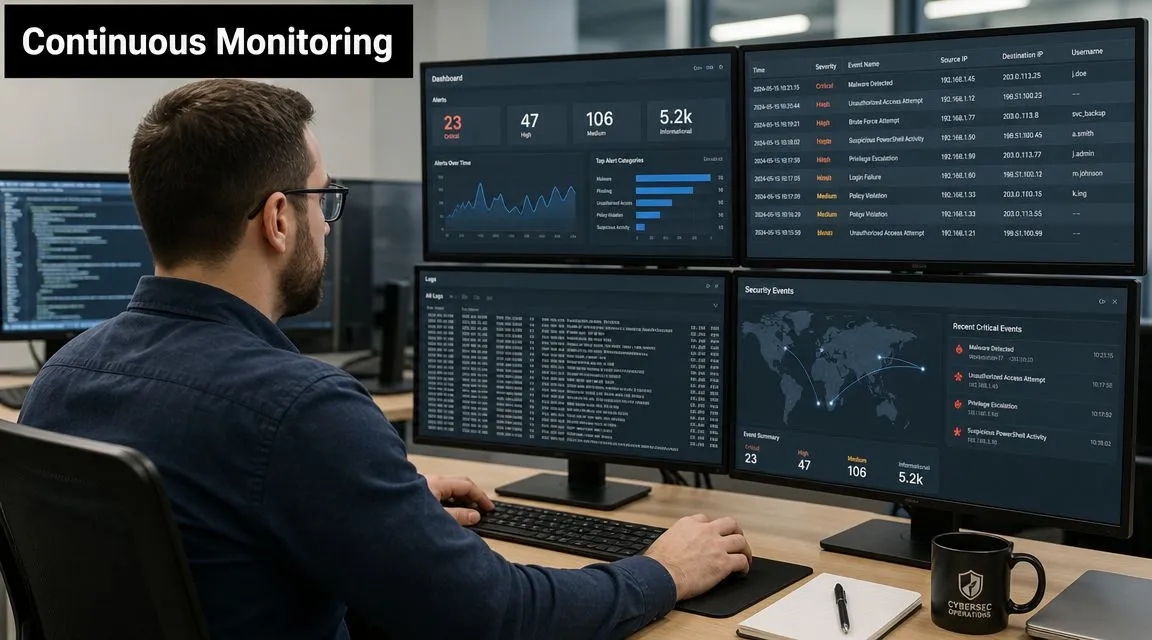
PCI guidance gets very specific here. It calls for quarterly external and internal vulnerability scans, annual penetration testing, and retention of at least one year of logs, with the most recent three months readily accessible for review (PCI SSC quick guide timing requirements). Those deadlines are what turn a generic security stack into an actual compliance operating model.
This is where SIEM earns its budget
A mature SIEM or SIEM/XDR platform centralizes logs from firewalls, endpoints, cloud services, databases, identity systems, and payment applications. It preserves evidence, supports alert triage, and lets teams prove that suspicious access, configuration changes, malware events, and test results were reviewed in context. That’s the practical value of a platform like UTMStack, especially when paired with centralized log management for audit evidence and retention.
One of the clearest market signals behind this shift is tooling demand. An independent market report projects the global PCI compliance software market to reach USD 1.79 billion in 2026 and USD 3.81 billion by 2035, representing a 9.2% CAGR (Business Research Insights PCI compliance software market projection). The reason is easy to see on the ground. Manual evidence collection doesn’t scale when logs, assets, users, and cloud services keep changing.
Use these controls as the daily engine of the PCI DSS compliance checklist:
- Aggregate logs centrally: Pull from endpoints, firewalls, cloud platforms, databases, IAM, and payment systems.
- Protect log integrity: Restrict deletion and unauthorized modification.
- Review alerts in context: Correlate identity, endpoint, and network events before escalating.
- Track scan cadence: Missed quarterly scans are simple findings that shouldn’t happen.
- Tie pen tests to remediation: A report without closure evidence is half a control.
- Run file integrity monitoring on critical systems: Especially where payment applications or sensitive configs live.
If Requirement 10 and 11 are weak, every other requirement becomes harder to prove, even when the underlying control exists.
PCI DSS 10-Requirement Comparison Matrix
| Requirement | 🔄 Implementation complexity | ⚡ Resource requirements | 📊 Expected outcomes | 💡 Ideal use cases | ⭐ Key advantages |
|---|---|---|---|---|---|
| Requirement 1: Install and Maintain Firewall Configuration | Medium-High, complex rule sets & segmentation | Medium, firewalls, monitoring staff | ⭐⭐⭐⭐, strong network isolation; audit trails | Segmentation of CDE, multi-datacenter networks | Prevents unauthorized access; reduces attack surface |
| Requirement 2: Do Not Use Vendor-Supplied Defaults for System Passwords | Low, procedural change across assets | Low, inventory & enforcement tools | ⭐⭐⭐, eliminates common default-credential risks | New system deployments, device provisioning | Removes low-hanging fruit; simplifies audits |
| Requirement 3: Protect Stored Cardholder Data | High, encryption/tokenization design & key mgmt | High, crypto, key management, storage changes | ⭐⭐⭐⭐, data rendered unusable if stolen | Databases, backups, removable media | Minimizes breach impact; defense-in-depth for data |
| Requirement 4: Encrypt Cardholder Data in Transit Across Public Networks | Medium, TLS configuration and cert mgmt | Medium, certs, scanning, monitoring | ⭐⭐⭐⭐, prevents MITM and protects integrity | Web apps, APIs, payment endpoints | Protects data in transit; builds customer trust |
| Requirement 5: Protect Systems Against Malware | Medium, endpoint coverage and EDR tuning | Medium-High, EDR/AV agents, SOC integration | ⭐⭐⭐⭐, faster detection; reduced dwell time | Workstations, servers, remote devices | Reduces malware-driven breaches; enables automated response |
| Requirement 6: Develop and Maintain Secure Systems and Applications | High, SDLC changes, testing, training | High, SAST/DAST, patch mgmt, developer resources | ⭐⭐⭐⭐, fewer vulnerabilities in production | CI/CD pipelines, in-house applications | Prevents app-layer flaws; speeds patching & remediation |
| Requirement 7: Restrict Access to Cardholder Data by Business Need-to-Know | Medium-High, RBAC design & reviews | Medium, IAM tooling, periodic reviews | ⭐⭐⭐⭐, limits exposure from compromised accounts | Role-driven organizations, large user bases | Enforces least privilege; simplifies audits |
| Requirement 8: Identify Users and Authenticate Access to System Components | Medium, unique IDs, MFA deployment | Medium, identity systems, MFA, logging | ⭐⭐⭐⭐, strong authentication; auditability | Administrative access, SSO/MFA rollouts | Reduces account compromise; enables traceability |
| Requirement 9: Restrict Physical Access to Cardholder Data | Medium, physical controls & visitor processes | Medium-High, badges, CCTV, secure storage | ⭐⭐⭐, prevents device/media theft; supports forensics | Data centers, on-prem storage of media | Blocks physical theft; provides evidentiary logs |
| Requirement 10 & 11: Track/Monitor Access & Regularly Test Systems | Very High, centralized logging, testing program | Very High, SIEM/SOAR, storage, scanners, staff | ⭐⭐⭐⭐⭐, comprehensive visibility; rapid detection | Regulated environments, continuous monitoring programs | Full audit trail; automates detection, scanning, reporting |
From Checklist to Continuous Compliance
PCI DSS programs rarely fail because teams do not have a checklist. They fail because evidence is scattered across firewalls, identity systems, endpoints, ticketing tools, scanners, and spreadsheets. By the time the assessor asks for proof, the team is reconstructing history instead of showing an operating control set.
A strong PCI DSS compliance checklist works best as a continuous control program tied to the full cardholder data environment and to the daily systems that generate evidence. That changes the job. Quarterly scans, annual penetration tests, access reviews, log retention, malware response, and change validation stop being isolated audit tasks and become part of normal security operations.
The practical advantage of a SIEM/XDR-centered model is simple. The same telemetry used to detect attacks can also prove that controls remained in place. Firewall rule changes, privileged access events, failed log collection, endpoint detections, vulnerability findings, and configuration drift should be visible in one place, with timestamps, ownership, and retention aligned to audit needs.
Under PCI DSS 4.0, the harder question is no longer whether a control existed at one point in time. The harder question is whether the team can show that the control stayed effective after patch cycles, personnel changes, cloud migrations, emergency firewall updates, and application releases. Many teams can produce policies and screenshots. Fewer can show when logging stopped on a payment server, when an admin role expanded beyond scope, or whether a segmentation change was reviewed and tested after implementation.
That is why mature PCI programs reduce manual collection wherever possible. Keep scope tight. Minimize stored cardholder data. Standardize system builds. Centralize authentication, logging, and alerting. Review privileged access on a schedule that matches risk, not just the audit calendar. Preserve evidence as part of the control itself, so the record exists before anyone asks for it.
Automation matters most where the work is repetitive and easy to miss. Examples include alerting on disabled log sources, correlating malware events with in-scope assets, flagging unauthorized firewall changes, tracking overdue remediation from vulnerability scans, and retaining access review records with clear approval history. Those steps do not replace control owners or assessor judgment. They reduce blind spots and make exceptions easier to investigate.
I use a simple test with security teams. If an assessor asked tomorrow for evidence of recent segmentation changes, privileged access reviews, anti-malware actions, quarterly scan results, retained security logs, and remediation from the last pen test, could the team produce it in hours instead of days? If not, the checklist still depends too heavily on manual follow-up.
Payment data keeps its value, so PCI work does not become easier by waiting for the audit window. The programs that hold up under scrutiny usually have the same traits. Clear scope. Consistent evidence. Automated monitoring. Fewer handoffs. That is how a checklist becomes a continuous compliance process.
For a line-by-line walk through Requirement 10, see PCI DSS 4.0 logging requirements.