A breach doesn’t become expensive only when systems go down. It becomes expensive when an organization spends months discovering what happened, who needs to decide, what evidence was lost, and which business services can’t wait. According to IBM’s 2024 Cost of a Data Breach Report, the global average cost of a data breach reached $4.88 million in 2024, while the average time to identify a breach was 194 days.
That reframes security incident response immediately. This isn’t just an IT cleanup function. It’s a business continuity discipline that sits at the intersection of SOC operations, executive decision-making, legal exposure, customer trust, and recovery planning. Teams that treat it as a ticket queue usually discover the gap too late, when counsel is asking for facts, leadership wants timelines, and analysts are still trying to confirm scope.
The practical challenge is that most incident response content stops at the SOC boundary. Real incidents don’t. They spill into compliance, communications, HR, eDiscovery, insurance, third-party responders, and sometimes law enforcement. A mature response program has to handle both tracks at once: the technical workflow that contains the attacker, and the business workflow that keeps the organization functioning under pressure.
The True Goal of Modern Incident Response
Security incident response is often described as detecting, containing, and remediating threats. That’s correct, but it’s incomplete. In practice, the primary job is to reduce business harm while preserving decision quality.
Why response is different from troubleshooting
Troubleshooting fixes a broken system. Incident response manages an adversarial event. That difference matters.
When an email gateway fails, the team restores service. When an attacker gains access to a mailbox, the team has to answer harder questions. Was data accessed? Which accounts were used? Does legal need to preserve evidence? Are regulators or customers affected? Can the user’s device still be trusted? Those decisions can’t be made by the SOC alone.
A useful way to frame it is this: troubleshooting restores functionality, but security incident response restores functionality, limits spread, preserves facts, and supports downstream decisions. If you skip the evidence and coordination parts, you may get systems back online faster and still fail the incident.
Practical rule: If the event could trigger legal review, executive reporting, customer notification, or an insurance claim, you’re not dealing with a purely technical problem anymore.
Leaders who need a concise executive framing can use resources like this CTO’s guide to incident response, which explains the decision-making side clearly enough for non-SOC stakeholders without flattening the technical realities.
What good incident response protects
The first objective is to minimize impact. That usually means limiting lateral movement, stopping ongoing abuse, and protecting business-critical systems before the team has perfect certainty.
The second is to restore services safely. “Safely” matters. Restoring a compromised identity, a poisoned host, or an unverified backup only resets the clock for the next outage.
The third is to preserve evidence. Teams under pressure often see this as paperwork. It isn’t. Without evidence preservation, root-cause analysis gets weaker, legal review gets riskier, and remediation gets repetitive because nobody can prove what happened.
A mature program also protects trust. Customers, boards, regulators, and business owners don’t judge incident response only by whether the malware was removed. They judge it by whether the organization acted coherently under stress.
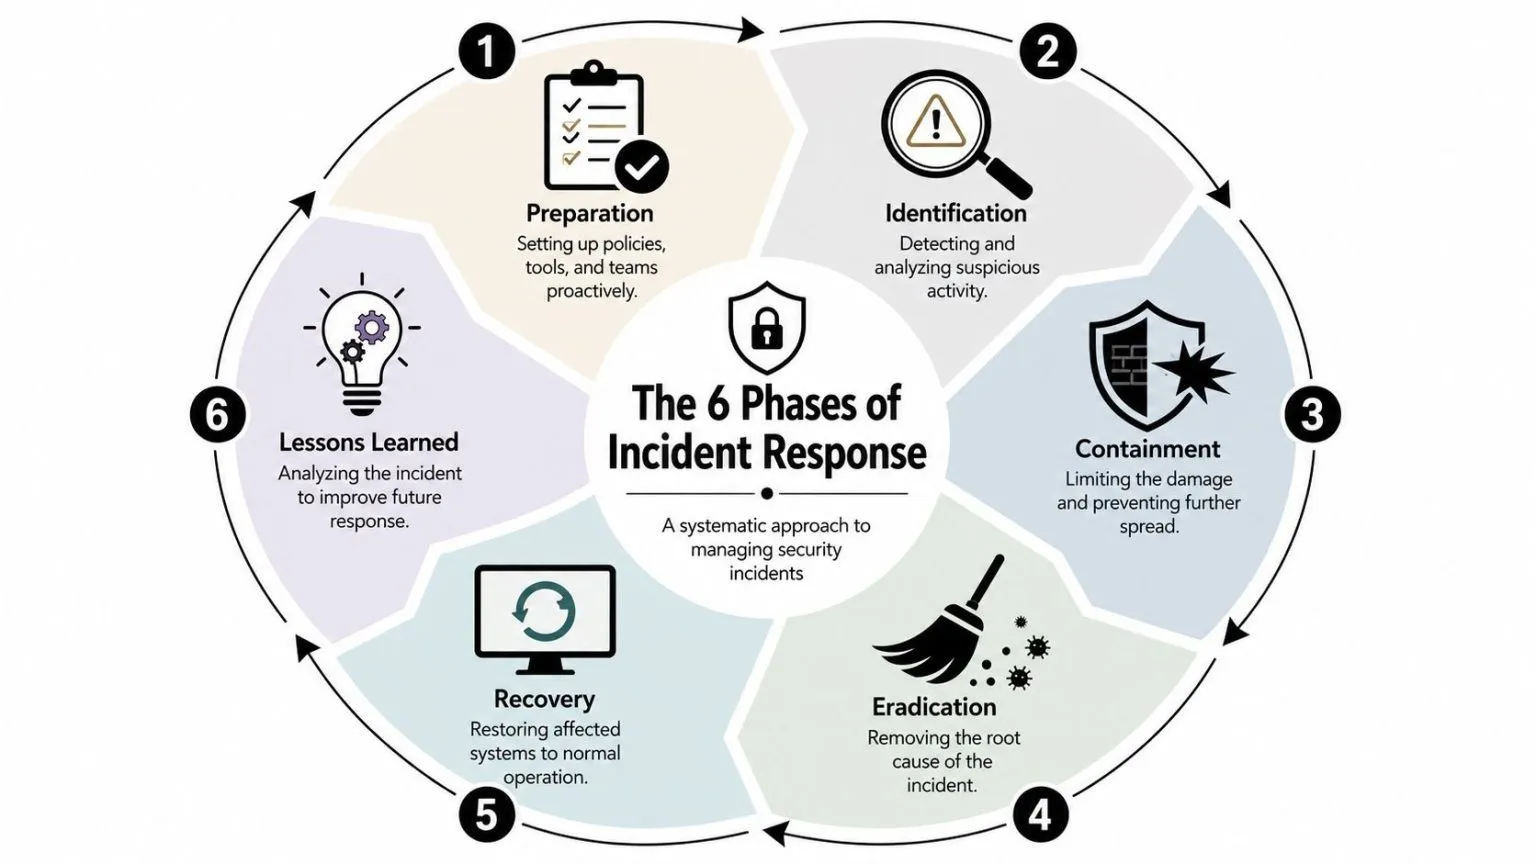
The 6 Phases of the Incident Response Lifecycle
The lifecycle gives teams a repeatable operating model. A mature incident response program is built around preparation, identification, containment, eradication, recovery, and lessons learned, with containment serving as the highest-value control point for limiting blast radius, as described in Atlassian’s incident response guidance.
Preparation
Preparation is where most response quality is decided. Not because it prevents every incident, but because it determines whether people know what to do when time gets compressed.
This phase includes response policies, escalation thresholds, contact trees, logging coverage, forensic readiness, backup validation, access to emergency tooling, and pre-approved playbooks. It also includes business decisions such as who can authorize isolation of a production server, who engages outside counsel, and who speaks to customers or regulators.
Teams often underinvest here because it doesn’t feel urgent. Then the first live incident becomes a workshop on missing prerequisites.
Identification
Identification starts when a signal becomes credible enough to investigate. That signal might come from SIEM correlation, EDR telemetry, a user report, cloud alerts, suspicious authentication activity, or third-party notification.
The goal isn’t to prove every detail immediately. The goal is to determine whether the activity is benign, suspicious, or an active incident that requires coordination. Good analysts ask a narrow set of early questions: what happened, what’s affected, what’s still ongoing, and how confident are we?
A common mistake is waiting for certainty before escalating. In real operations, early escalation with clear confidence levels works better than late escalation with perfect language.
Containment
Containment is where response establishes control. If identification tells you what may be happening, containment stops the incident from getting worse while the rest of the investigation catches up.
Short-term containment might include isolating endpoints, disabling accounts, revoking sessions, blocking malicious indicators, or segmenting systems. Longer-term containment may involve traffic restrictions, temporary configuration changes, or increased monitoring around critical assets while eradication planning continues.
Containment decisions should be tied to business criticality, not analyst preference. Isolating the wrong system can create a self-inflicted outage.
This is why mature teams build tiered containment options in advance. “Full isolation” and “monitor only” aren’t the only choices. There should be middle states that balance evidence preservation, service availability, and attacker disruption.
Eradication
Eradication removes the cause of compromise. That can mean deleting malware, removing persistence, rotating credentials, patching exploited software, decommissioning unsafe assets, or rebuilding systems from known-good baselines.
This phase is where weak scoping hurts. If the team eradicates on the originally affected host but misses adjacent compromised accounts or shadow persistence, the incident returns under a different alert name. Good eradication is evidence-driven and scope-aware.
A strong practice here is to define exit criteria before changing systems. For example: all known compromised accounts reset, persistence checks completed, detections tuned for re-entry, and affected assets validated by both operations and security.
Recovery
Recovery returns systems to production with heightened scrutiny. It isn’t the same as eradication. Eradication removes the problem. Recovery proves the business can run again without reintroducing risk.
Teams should sequence recovery based on business criticality. Identity services, communication platforms, transaction systems, and regulated data environments may all require different validation steps. Monitoring should tighten during this period, because attempted re-entry often shows up when the attacker realizes access has been disrupted.
A rushed recovery usually creates two problems: unstable operations and incomplete confidence.
Lessons learned
The final phase is where organizations either mature or repeat themselves.
A useful review doesn’t stop at “user clicked phishing email” or “server was unpatched.” It looks at detection gaps, escalation delays, unclear approvals, communications friction, evidence gaps, and the points where the business side and technical side lost alignment.
Use the review to update playbooks, improve detections, revise ownership, and refine decision thresholds. If the same class of incident happens again, the organization should handle it differently the second time. Otherwise, the meeting was just therapy.
Building Your Response Team and RACI Matrix
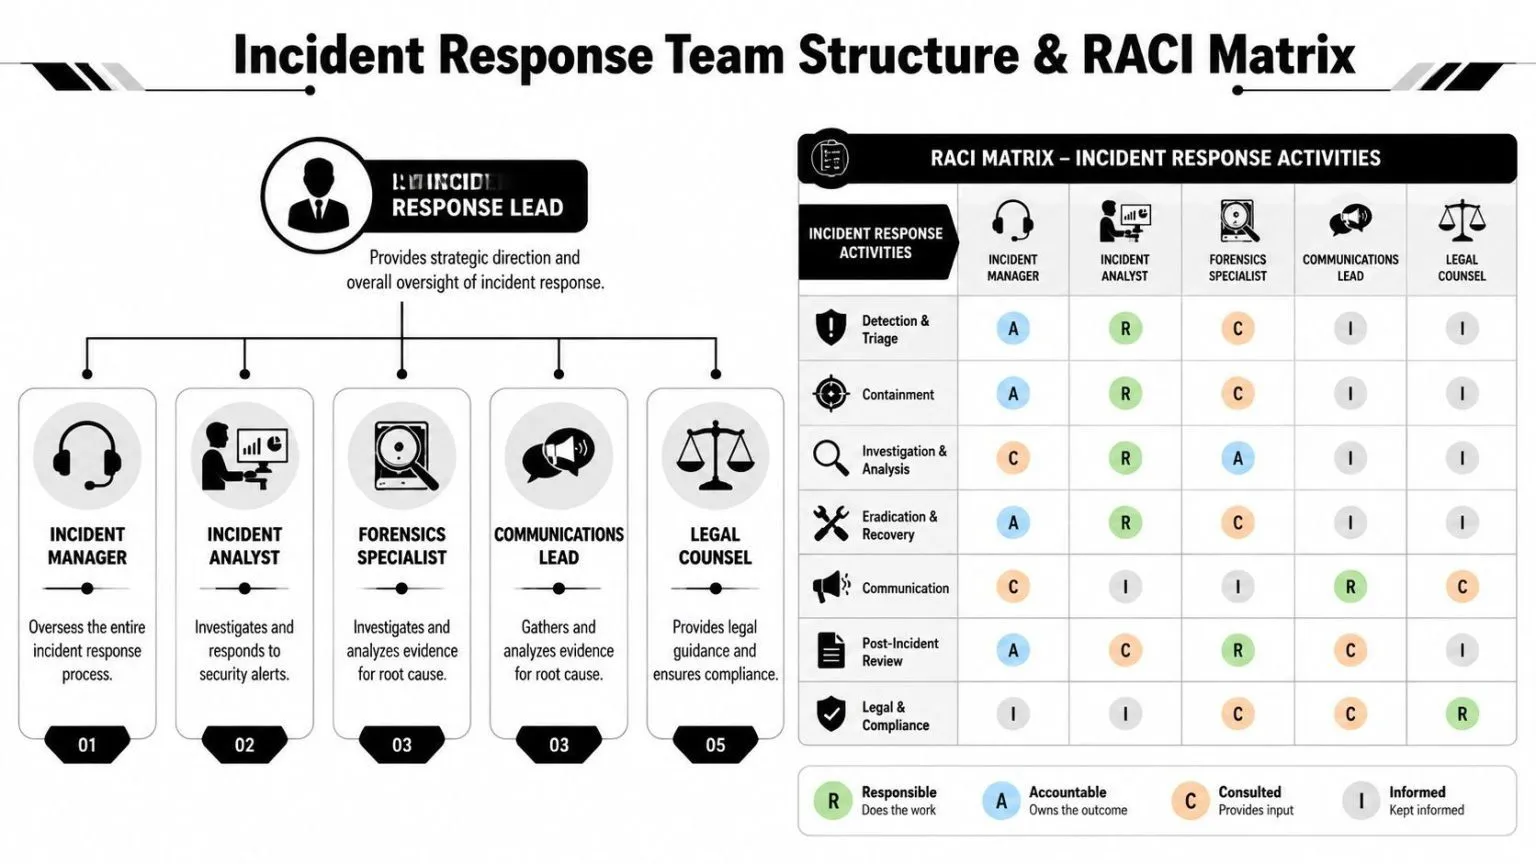
Tools don’t resolve ownership. In a live incident, unclear responsibility wastes more time than missing dashboard widgets. The strongest teams decide in advance who investigates, who authorizes, who advises, and who needs updates.
Who needs to be in the room before an incident starts
Most organizations can name their SOC analyst and security lead. Fewer can say who owns evidence retention, employee matters, customer messaging, or law-enforcement coordination. That gap is common. Wiz’s incident response framework overview notes that many teams still treat response as a SOC-only workflow and fail to pre-plan for legal, regulatory, and operational escalation.
A practical core team usually includes:
- Incident commander: Owns coordination, priorities, and decision flow. This role keeps the response moving and prevents technical threads from fragmenting.
- Technical lead: Directs investigation, containment, and remediation across affected systems.
- SOC analyst or analysts: Validate alerts, build timeline detail, pivot across telemetry, and track scope.
- Forensics specialist: Preserves and analyzes evidence where root cause, legal exposure, or insurer requirements matter.
- Communications lead: Manages internal updates and external messaging with legal review.
- Legal counsel: Advises on preservation, disclosure, privilege, contracts, and regulatory obligations.
- IT operations or platform owners: Execute changes on infrastructure, cloud, identity, and endpoint systems.
- HR or people operations: Needed when employee accounts, insider activity, or disciplinary questions are involved.
For teams formalizing those responsibilities, role descriptions like Threat detection and response roles can help translate broad incident response expectations into accountable job functions. It also helps to anchor the team design to the broader SOC operating model, because handoffs fail when detection and response are designed separately.
How a RACI prevents wasted time
A RACI matrix gives each major task four lenses: who is Responsible, who is Accountable, who must be Consulted, and who should be Informed. The value isn’t the spreadsheet itself. The value is removing ambiguity before the crisis.
Here’s a simple example:
| Activity | Responsible | Accountable | Consulted | Informed |
|---|---|---|---|---|
| Triage suspicious alert | SOC analyst | Technical lead | System owner | Incident commander |
| Isolate endpoint | IT operations | Incident commander | Technical lead, business owner | Legal, leadership |
| Approve customer communication | Communications lead | Executive sponsor | Legal, incident commander | Support teams |
| Preserve forensic evidence | Forensics specialist | Legal counsel | Technical lead | Executive sponsor |
Without this clarity, teams argue over authority in the middle of containment. With it, people can move fast without improvising governance.
The first hour of an incident should be spent executing decisions, not discovering who’s allowed to make them.
Actionable Playbooks for Common Threats
Playbooks are where strategy becomes executable. A good playbook doesn’t try to predict every branch. It gives the team a working sequence, clear triggers, and enough structure to keep the response coherent when pressure rises.
Ransomware playbook example
A ransomware event usually doesn’t begin with the ransom note. It often starts with endpoint alerts, suspicious privilege use, mass file change behavior, disabled security controls, or authentication patterns that don’t fit the user or host.
A practical ransomware playbook usually starts like this:
- Validate the trigger. Confirm whether the activity is encryption, pre-encryption staging, destructive behavior, or a false positive caused by legitimate software.
- Classify impacted scope. Identify affected hosts, users, shares, administrative accounts, and connected systems.
- Contain quickly. Isolate compromised endpoints, restrict privileged accounts, and segment systems that show signs of lateral spread.
- Preserve evidence. Capture volatile data where feasible, retain relevant logs, and avoid wiping hosts before forensics and legal review.
- Assess business impact. Determine which critical services are affected and whether recovery decisions depend on application dependencies or backup integrity.
- Eradicate and rebuild. Remove persistence, rotate credentials, patch exploited paths, and rebuild high-risk systems from trusted baselines.
- Recover in waves. Restore the most critical services first, then monitor aggressively for recurrence.
What works is decisive containment paired with disciplined scoping. What doesn’t work is restoring systems while the team still has active privileged compromise or unknown lateral movement.
Business email compromise playbook example
Business email compromise is a different kind of incident. It often looks less dramatic than ransomware, but it can create payment fraud, data exposure, and executive escalation very quickly.
A practical mailbox compromise playbook should include:
- Confirm the compromise path: Review sign-in patterns, mailbox rules, delegated access, and unusual message activity.
- Protect the identity first: Reset credentials, revoke active sessions, rotate MFA factors if needed, and review related accounts.
- Search for spread: Look for similar phishing emails, affected recipients, inbox rule abuse, and message forwarding behavior across the environment.
- Contain business damage: Alert finance, procurement, and executive assistants if payment requests, invoice changes, or sensitive conversations may be involved.
- Preserve communication evidence: Save relevant email artifacts, timestamps, and administrative actions for legal review and root-cause analysis.
- Communicate with precision: Notify internal stakeholders who may act on fraudulent requests. Broad messaging is fine later. Early messaging should be targeted and operational.
A phishing response fails when the team resets one account but ignores the business process the attacker was trying to exploit.
The strongest playbooks always include non-technical checks. If an attacker used an executive mailbox to influence a wire request, finance controls matter as much as mailbox cleanup.
The Technology Powering IR SIEM SOAR and XDR
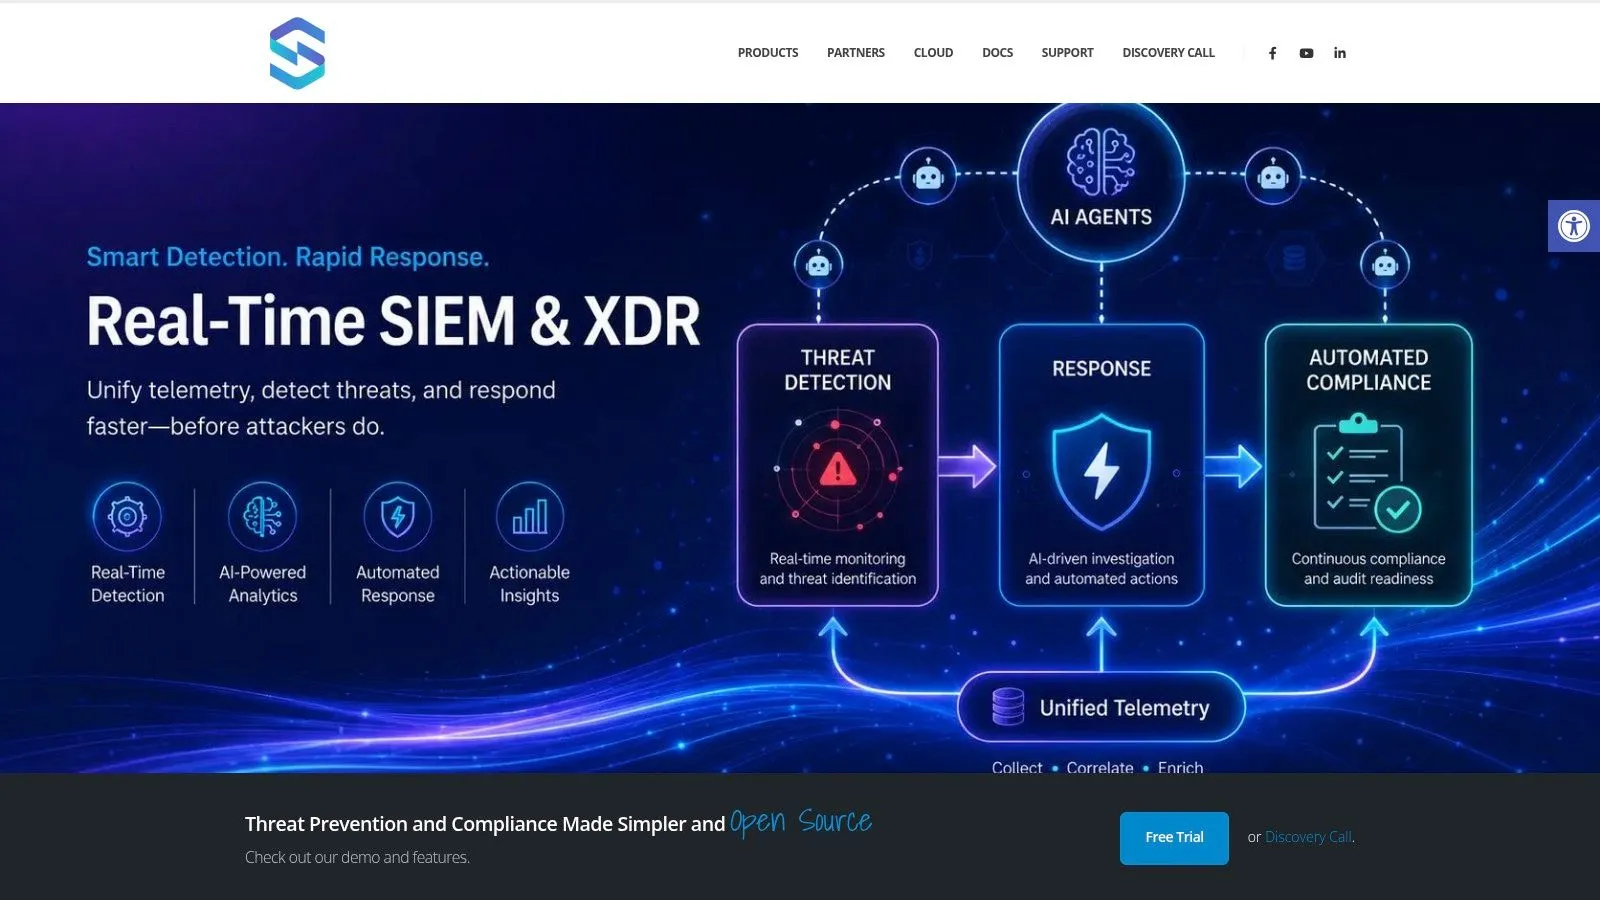
Technology doesn’t replace incident response discipline, but mature response is hard to sustain without the right telemetry and orchestration. The practical stack usually combines SIEM for log correlation, EDR for endpoint visibility and isolation, SOAR for automated playbooks, and XDR to unify signals across endpoint, network, and cloud into one investigation workflow, as described earlier in the lifecycle discussion.
What each platform layer actually does
A SIEM gives you the record of what happened across systems. It aggregates authentication events, cloud logs, firewall activity, application telemetry, and infrastructure signals so analysts can correlate patterns that a single tool wouldn’t catch alone.
An EDR platform gives direct visibility into host behavior. That matters when you need process lineage, suspicious execution chains, registry or persistence clues, and the ability to isolate an endpoint without waiting on another team.
A SOAR platform turns common response actions into controlled workflows. It can open cases, enrich alerts, notify stakeholders, disable accounts, create tickets, and launch containment steps with approval gates where needed.
XDR is useful when the incident crosses boundaries. A mailbox alert, a cloud login anomaly, and suspicious endpoint activity often belong to the same story. XDR helps analysts investigate that story in one workflow instead of stitching it together manually.
A short comparison helps:
| Capability | Primary use in response | Common failure mode |
|---|---|---|
| SIEM | Correlation, timeline, visibility across systems | Too much noise and weak normalization |
| EDR | Host investigation and containment | Incomplete endpoint coverage |
| SOAR | Repeatable actions and case workflow | Automating bad process design |
| XDR | Unified cross-domain investigation | Overreliance on vendor-defined logic |
How the stack supports the lifecycle
During preparation, teams need reliable log ingestion, case workflows, access controls, and tested automation. During identification, correlation rules and endpoint telemetry reduce blind spots. During containment, automation matters because repetitive manual steps are slow and error-prone. During eradication and recovery, integrated tooling gives the team evidence that actions changed risk.
One practical approach is using a platform that combines these functions instead of forcing analysts to pivot across disconnected consoles. UTMStack’s incident response automation and SOAR capabilities are an example of that model. It ingests logs, correlates events across sources, and supports automated response playbooks so teams can move from alert to action without rebuilding the workflow in separate products.
The trade-off is straightforward. More integrated tooling usually improves speed and consistency, but only if the organization has already defined approvals, escalation logic, and playbook quality. Automating a vague process just makes bad decisions happen faster.
Measuring Success and Mapping to Compliance
A response program should be measured like an operational function, not described like a policy document. If teams can’t show where time is lost, they can’t improve it.
Operational metrics that matter
The most useful metrics are the ones tied to handoffs and delays. Teams commonly track how long it takes to detect, validate, contain, eradicate, and recover. The value isn’t in reporting a vanity number to leadership. The value is exposing where the workflow stalls.
For example, a team may discover that technical triage is fast but approval for containment is slow. Or that mailbox compromises are detected quickly but root-cause validation lags because logs are fragmented. Those are process problems, not analyst effort problems.
A workable operating review should include:
- Detection quality: Which alerts became real incidents, and which sources generated high-noise triage.
- Containment delay: Where approvals, missing access, or business dependencies slowed action.
- Recovery confidence: Whether restored systems were validated with the right monitoring and ownership.
- Repeat incident patterns: Whether the same control gap keeps resurfacing across different incident types.
Reporting and evidence for auditors and counsel
Incident reporting is often treated as the final administrative step. That’s backwards. High-quality reporting is a forensic control. Guidance from Virginia Tech’s incident response management process emphasizes capturing the incident timeline, affected systems and accounts, attack vector, remediation steps, and communication logs so teams can support root-cause analysis and validate recovery.
That same reporting discipline supports compliance. Auditors and counsel usually want a defensible chain of events, evidence of control execution, and proof that recovery actions were verified. If the incident record is incomplete, teams are forced to reconstruct decisions from chat messages and memory.
Centralized evidence collection helps. A platform for centralized log management gives responders a single place to retain relevant telemetry, preserve timelines, and align technical facts with audit requirements across regulated environments.
Good reporting answers two questions at once: what happened, and how do we prove our response was appropriate?
When teams get this right, compliance becomes a byproduct of disciplined operations rather than a separate cleanup project after the incident closes.
Your Implementation Roadmap and Common Pitfalls
Most organizations don’t need a perfect program first. They need a workable one that can survive a real incident and then improve. The bigger risk is waiting until every policy, tool, and org chart looks complete.
A practical maturity path
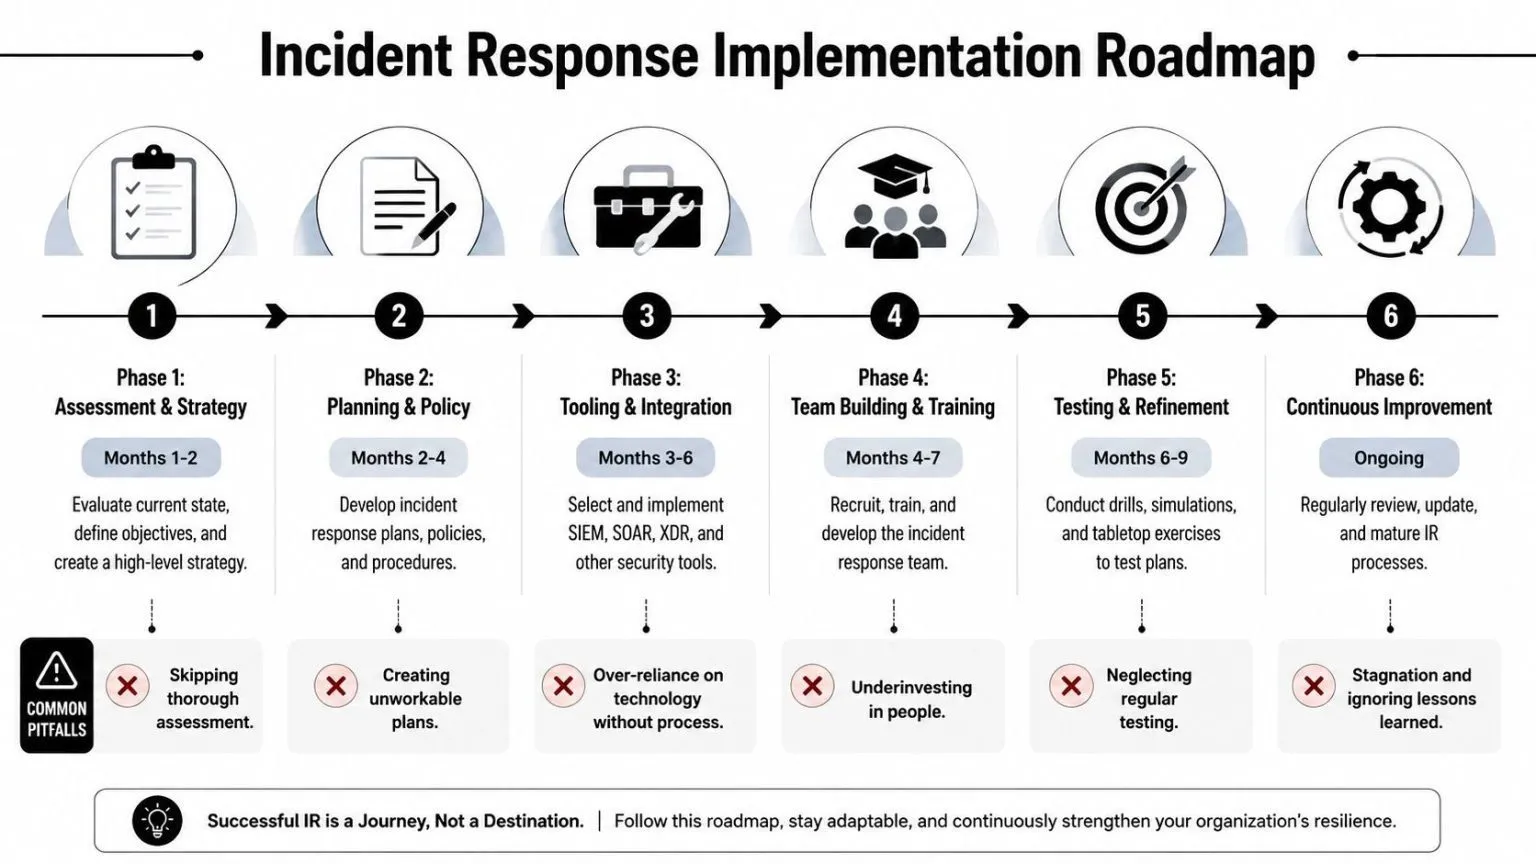
Start with an assessment of current telemetry, escalation paths, business dependencies, and authority lines. Then write the minimum viable response plan: severity criteria, incident roles, communication paths, evidence handling, and a short list of priority playbooks.
After that, integrate your tools with the process you intend to run. Then train the people who will execute it. That includes security, IT, legal, communications, and business owners. A plan that only the SOC understands isn’t a response program. It’s a local procedure.
The final step is repeated testing. CISA’s guidance on cybersecurity plans and assessments states that only 30% of organizations regularly test their incident response plans, which means 70% are relying on unverified strategies in a real crisis. That should be enough to settle the debate about whether tabletop exercises and simulations are optional. They aren’t.
Where teams usually fail
The most common failures are predictable:
- Untested plans: The document exists, but nobody has practiced decisions under time pressure.
- Unclear roles: Security, legal, IT, and leadership all assume someone else owns key calls.
- Tool-first thinking: The stack is deployed, but the playbooks, approvals, and handoffs are weak.
- Poor business integration: Teams know how to close alerts, but not how to manage disclosure, continuity, or executive updates.
For teams building the plan itself, this incident response plan overview is a useful external reference because it reinforces the need for a structured, testable operating model rather than a policy binder.
The organizations that improve fastest are usually the ones willing to run imperfect drills, find the weak points, and fix them before an attacker does.
If you’re building or maturing a security incident response program, UTMStack is one option to evaluate for unifying SIEM, SOAR, XDR, and compliance workflows in a single operating model. It’s especially relevant if your team needs centralized visibility, automated playbooks, and evidence collection without stitching together multiple disconnected tools.